 +1 (248) 723-7903
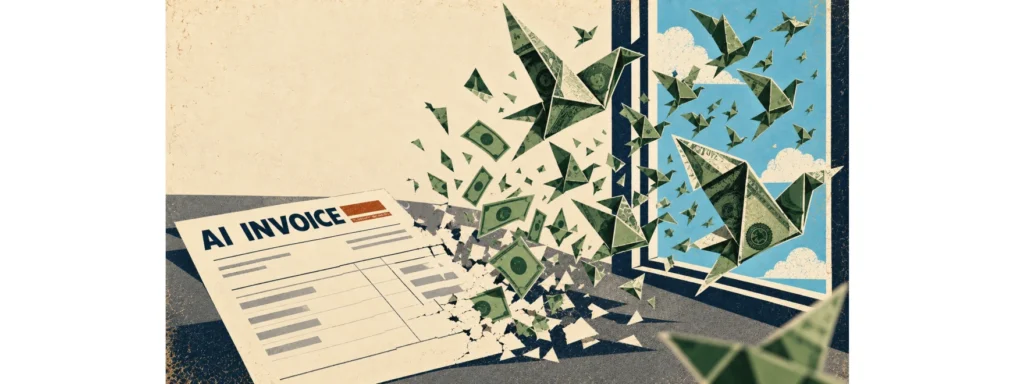
One of the most common frustrations I hear from business owners is that they know exactly what they spend on AI each month but still can’t say what it bought them. When their vendor bill arrives, it’s just a lump sum with no way to see how the usage breaks down against the work that got done.
Every other recurring cost in the business gets held to a standard. You know what an hour of labor costs, so when your payroll line climbs, you can see whether it was total hours that went up or the wage. AI should be held to the same standard, and that requires a rate.
Software used to make that rate easy. It was priced per person per month, so calculating the cost per user was one division away.
AI, on the other hand, is billed by material processed. Providers meter in tokens, which are chunks of text about three-quarters of a word long, and the size of any charge is set by how much the model reads and how much it writes. That number will be accurate, but it’s not particularly helpful as far as understanding your AI usage is concerned, because there’s no way to map “tokens used” to “work produced”. More tokens consumed doesn’t necessarily mean more work finished. One customer email might take a single request or six passes, and skimming a hundred-page contract for one date costs more than answering a short question.
The rate a business needs is what one completed piece of work costs. That number is simple math once you know what to look for, and it’s what tells you which tasks you’re overpaying for.
Identify bottlenecks, automate workflows, and build fast.
Get Started TodayMore and more software is moving to the token-based billing model.
GitHub recently moved every Copilot plan to usage-based billing. Its old plans charged per interaction, so a one-line question cost the same as an agent working through an entire codebase. The new plans charge for how much material the model processes and produces.
This change is causing big waves in the industry: Stripe paid roughly a billion dollars to acquire Metronome, a usage-based billing platform, and during this acquisition its CEO called metered pricing the native business model of the AI era.
Vendors who sold by the seat two years ago are adding usage charges on top, and products you already own are being repriced by usage as AI features get added to them.
So, the rate matters more each quarter, and calculating cost per unit of completed work becomes more critical with each passing day.
Define the unit of work with an outcome someone would recognize clearly as done.
Units of work from various areas of the business might be:
To get to AI cost per successful task, take the number of these success events you observe and divide the total AI spend for the task by this number. This is your average AI cost per successful task, over whatever time horizon you prefer to measure.
The task you measure and optimize has to be repetitive in order to benefit from this approach; this is because unless a task uses roughly the same amount of tokens every time it runs, there’s no stable rate of consumption to be had.
Highly variable tasks, like pure research, for example, would be a bad candidate to measure in this way because one question might get answered in a minute and consume few tokens while another could turn into an hour of follow-ups and consume orders of magnitude more.
That sounds like a serious limitation, but it’s really not. The tasks that qualify are the ones consuming most of your spending anyway. A task you run two thousand times a month costs more in total than a task you agonize over twice.
The task count is the easy half. The spending on just those tasks has to be tagged and broken out, because the standard bill you receive at the end of the month combines everything the tool did that month into a single figure.
How much tagging and how complex breaking out this spending is depends on where the task runs.
If it runs through a tool that only does that job, the work is already done for you. A tool built for invoice extraction bills you for invoice extraction, so its usage report is your numerator. This is a decent argument for building or buying narrow tools instead of running everything through one general assistant, and it’s a consideration most businesses never factor into the purchase.
If the task shares a tool with a dozen other jobs, you’ll have to measure a sample, or tag the usage.
If you don’t have a way to tag the usage to break out the spending by task type (like a separate API key for that task), run the task a few times while watching what the tool reports for consumption, take the average, and multiply by the number of times the tool ran last month. This result is an estimate, but it’s accurate enough for the decision in front of you, which is deciding whether the cost per successful task means the AI tool is worth running.
At higher volumes, businesses stop measuring samples and route every request through a gateway, which is a single piece of software that all AI traffic passes through on its way to the provider. Because everything goes through one door, the gateway can tag each request with the job it belongs to before sending it on. Per-task spending then comes out of the gateway’s own records. This is the best choice once the number of tasks and the size of the bill justify the setup, and the sample method covers you until then.
Once you have the rate for a task, the first thing it usually tells you is that you’re overpaying for something simple.
Think of it this way – if you ran a print shop, you wouldn’t put every job on the wide-format press. A single black-and-white copy would cost you the same as a full-color, high-resolution print on specialty paper.
A general-purpose model treats every job in a business the same way. It charges the same rate to sort an incoming email into one of four buckets as it does to draft a careful response to an unhappy customer. The response needs judgment; the sorting needs a rule applied consistently, and a much smaller model can run that rule for a fraction of the cost. Anthropic’s flagship model, Opus, costs five times as much as its smallest model, Haiku, for identical text.
In most of the companies I work with, routine work makes up most of their AI usage – things like categorizing, extracting, checking, and routing. All of these tasks represent a narrow question with a single correct answer. Sending basic tasks to the most capable model is a default rather than a decision, and it’s one of the most expensive habits I see in AI right now.
Once you know what a task costs, you have options available that you didn’t back while the bill was a single number. They run roughly from easiest to most complicated:
Move to a smaller model. Providers sell several tiers, and a task with one right answer will often run on the cheapest one with no drop in quality. Testing it costs nothing but the time.
Send less material. Every run is priced by what the model reads, so a workflow that hands over an entire document when four fields would do is paying for the rest of that document every single time.
Stop paying twice. If every run includes the same instructions or the same reference material, most providers will charge a fraction of the normal rate for the repeated part. It’s called prompt caching, and it has to be switched on deliberately. Plenty of businesses never take advantage of this.
Replace the model entirely. A classical machine learning model is a small program trained on examples to do exactly one thing, like sorting items into categories or scoring how likely something is. It runs for a fraction of what a general model costs. Small businesses never used to build these, because it was expensive. But premium AI models themselves can now handle the specialized setup. This is a good option for businesses repeating a single task at high volume.
Every one of these solutions depends on knowing your AI cost per task. Without it, there’s no way to separate the spending that’s working from the spending that’s wasteful, and only two options are left.
The more work you give to AI, the more both of those situations will cost you, and nobody I know is handing less work to AI next year – which means the cheapest time to get a handle on it is now.
What’s the one task your company completes most often, and what does one completion cost you? Find that number, and it’ll tell you whether you’re overpaying for something a cheaper tool could handle. Without it, every decision you make about that spending is a just a guess.
If your AI spending has grown past the point where anyone can explain it, an outside perspective can help. Schedule a free consultation with Michael Weinberger to work out what your AI bill is actually buying. mweinberger@proactivemgmt.com
Identify bottlenecks, automate workflows, and build fast.
Get Started Today
I’d love to help you with your tech needs. Just let me know how to reach you and when’s a good time to talk.
"*" indicates required fields
